Blog
Build logs
Write-ups from my experiments folder. One post per experiment: what I set out to test, the exact numbers I measured, and the parts that did not work. Failures get the same space as results, because that is where the useful information is.
I finished 5th of 232 on a Kaggle wearables challenge.
0.92497 to 0.93825 public, 0.93137 private. What moved the score, a leak that looked like a gain, and why every top team dropped.
Read the write-up ->
I put a decision model in front of my portfolio chatbot.
Keyword rules blocked 12 of 20 real questions; regex let 10 of 12 jailbreaks through. A typed decision model got both to zero on the same 50 labelled messages.
Read the write-up ->
I shipped a Weights & Biases sink for robot evals. Here is how it works.
inspect-robots-wandb v0.1.0 is on PyPI: one W&B run per Inspect Robots evaluation, the full eval spec as config, and every aggregate metric.
Read the write-up ->
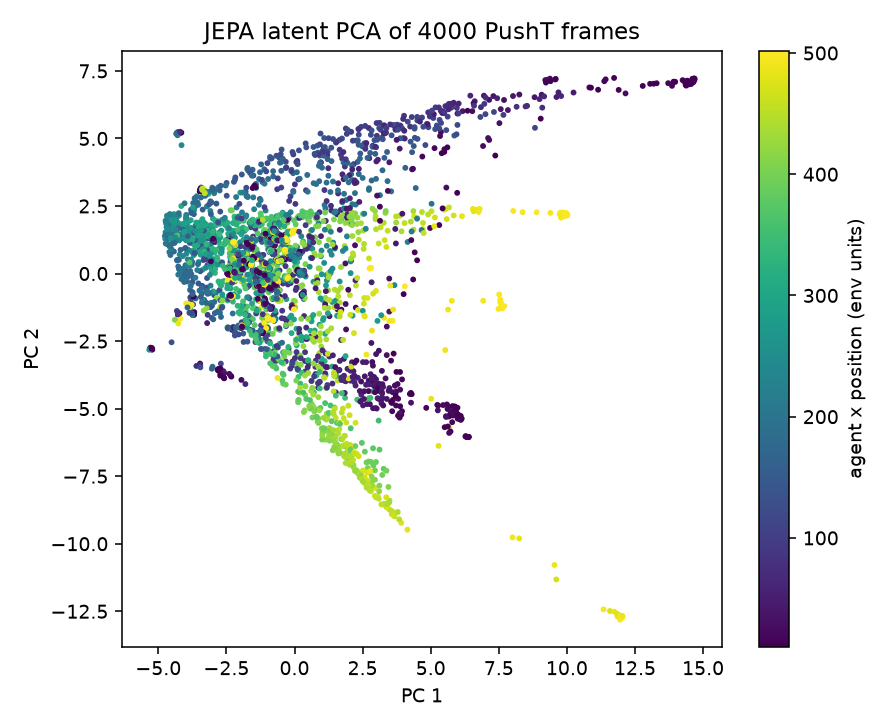
I trained a world model on my laptop. It learned physics and still could not push a block.
Experiment 01: a 1.9M-parameter JEPA world model on an 8 GB laptop GPU — seven minutes of training, emergent physical state, and a planner that scored exactly zero.
Read the write-up ->